Integrating AI into live fintech operations without causing outages, data loss, or compliance violations is not a theoretical problem. It's an execution problem. The framework itself is straightforward: isolate development, test rigorously in staging, deploy gradually to production. Where teams fail is in the discipline required to actually follow it. A misconfigured model can breach regulatory requirements or crash customer-facing systems before anyone catches it.
The difference between teams that deploy AI successfully and those that don't comes down to one thing: defining measurable business objectives before writing any code. Instead of "improve fraud detection," target something specific: "reduce false positives by 10% over six months while maintaining steady true positive rates." This clarity guides development and simplifies auditing.
Last verified: November 3, 2026
Quick answer: How to move AI from sandbox to live without breaking compliance or service
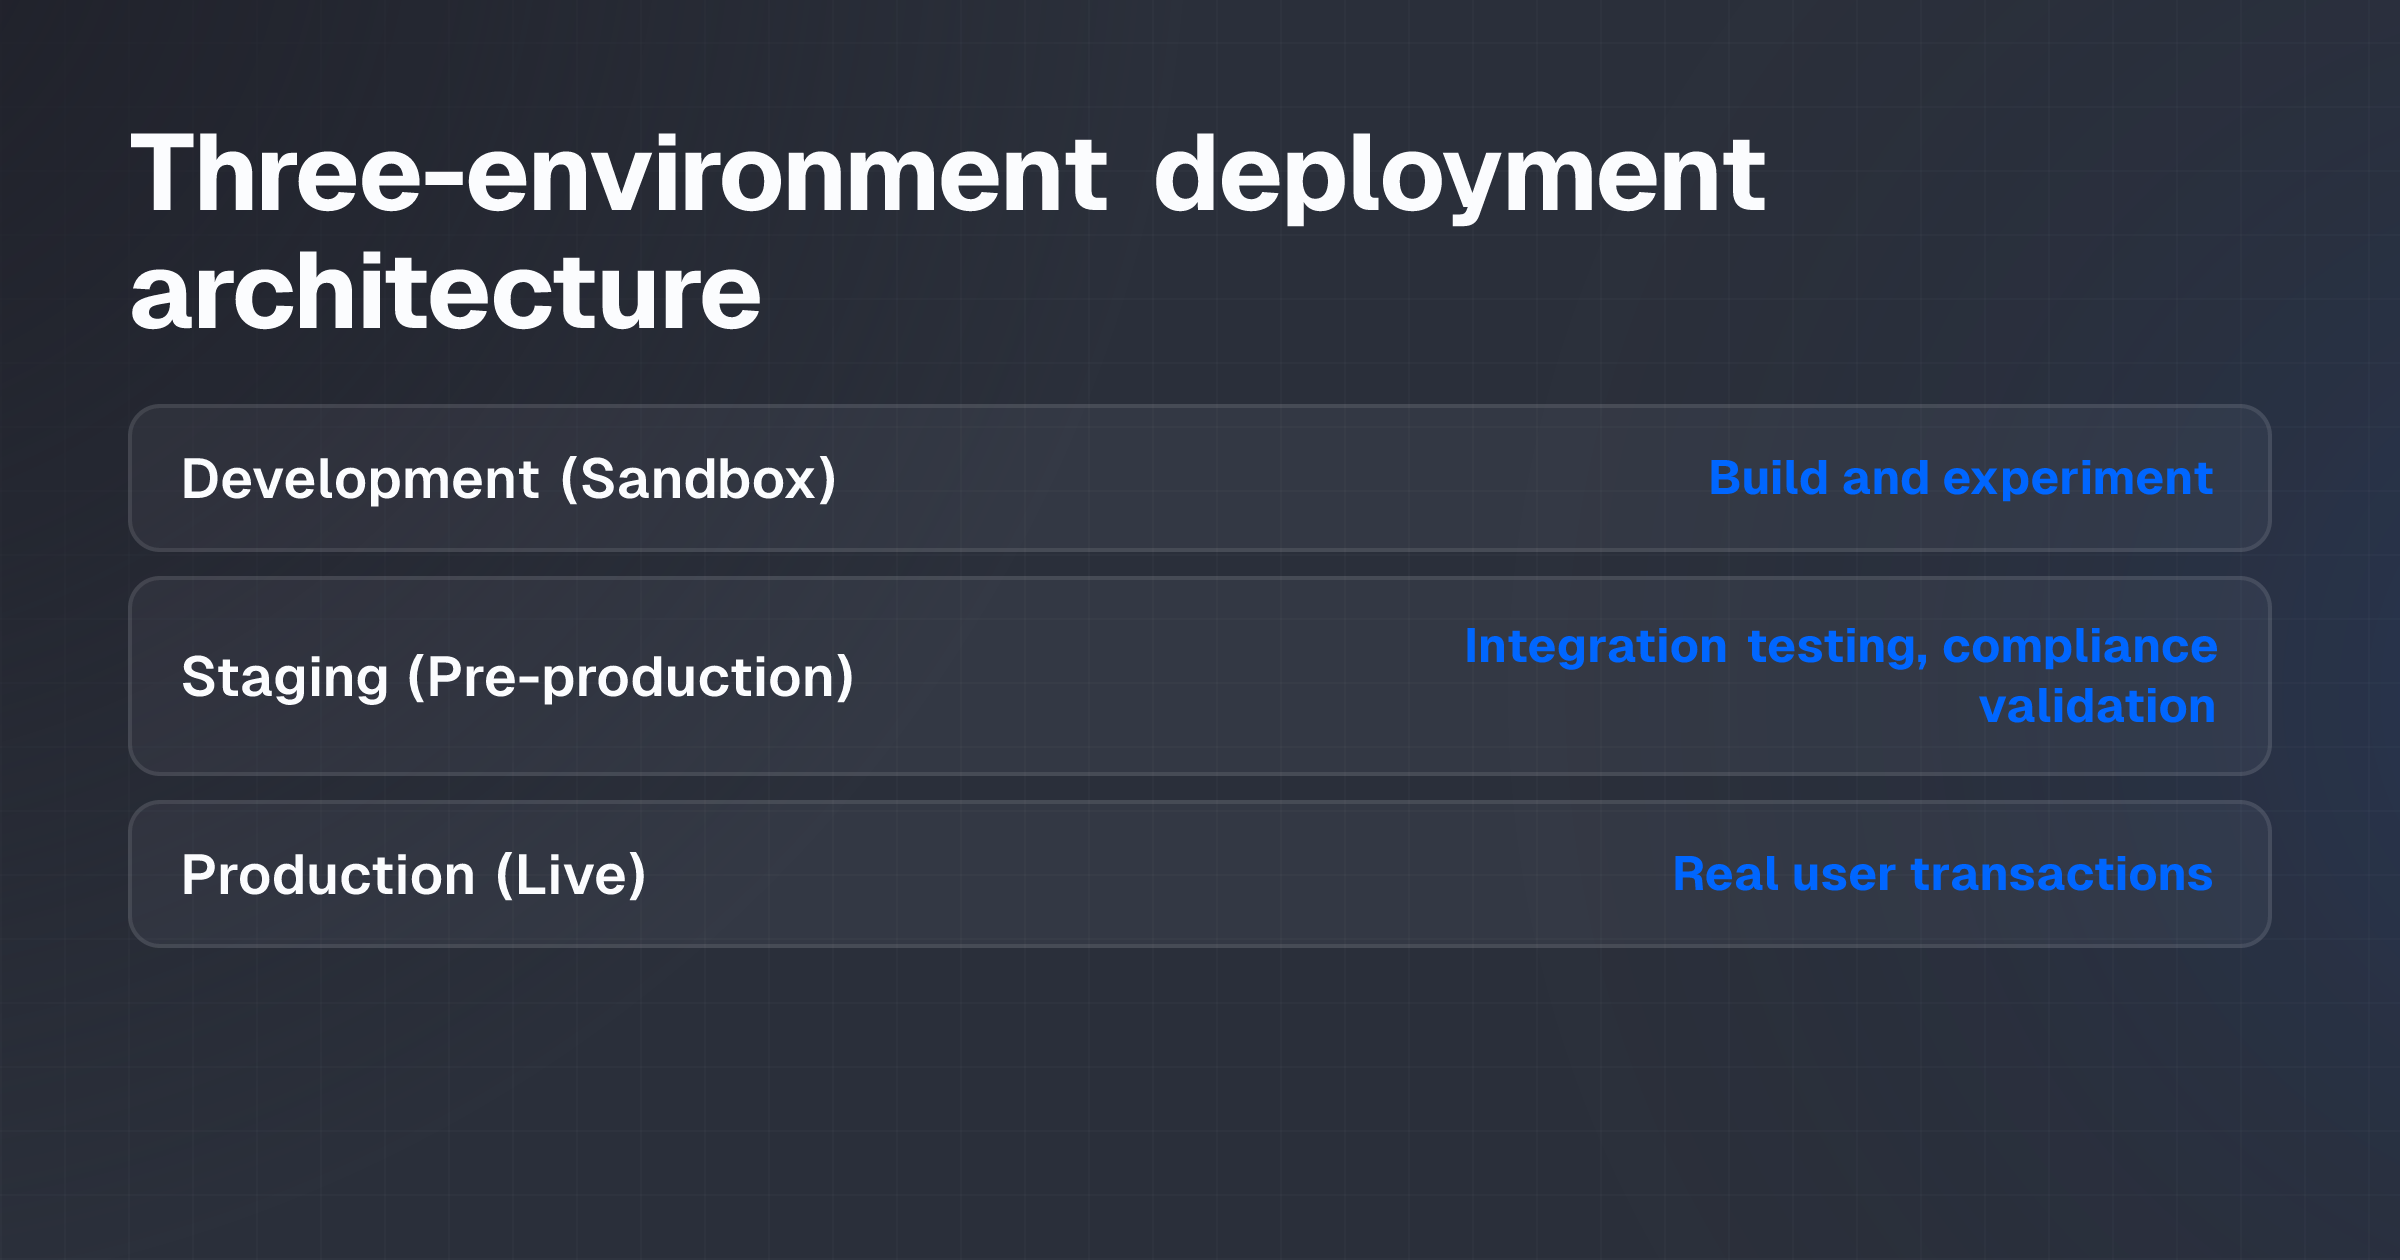
AI deployment in fintech requires three sequential environments:
- Development (Sandbox): Isolated space for engineers to build and experiment. No production data. No live systems affected.
- Staging (Pre-production): A near-identical replica of production, used for integration testing, security checks, performance benchmarking, and compliance validation before rollout.
- Production (Live): Where real users interact with the system and transactions occur in real time.
Moving between these environments is not automatic. Each stage has pass/fail criteria, specific performance thresholds, security validations, compliance checks. Only when those criteria are met does the AI move forward.
Successful operators define what success looks like before development begins. Not vague goals. Specific targets. What percentage of fraud reduction are you aiming for? By what margin should risk assessment outperform the previous method? How much should personalized recommendations lift engagement? Quantifiable targets matter. They guide the build and simplify the audit.
What actually got deployed: Three-environment architecture with gradual rollout techniques
Successful fintech AI deployments follow a repeatable pattern. Build in isolation. Validate in near-production. Release to live users gradually.
Development environment
Engineers build and train models using sandbox infrastructure fully separated from staging and production systems. Data used here is either anonymized or synthetic, never live customer information.
The purpose is experimentation without risk. Teams test multiple model architectures, retrain on new data patterns, iterate rapidly without concern for service impact.
Staging environment
Before touching production, the AI system undergoes comprehensive testing in an environment that mirrors production as closely as possible.
This includes data parity, staging uses representative or anonymized production data so testing reflects real-world conditions. System integration matters: the AI model is tested alongside existing fintech infrastructure, including payment processors, compliance reporting systems, customer databases. Performance benchmarking ensures the model performs within acceptable latency and accuracy bounds under realistic transaction volumes. Security assessment covers vulnerability testing and penetration testing of the AI system and its data pathways. Compliance validation tests the model's decisions and audit trails against regulatory requirements, AML, KYC, MiFID II, GDPR, and jurisdiction-specific rules.
Only when staging tests pass defined thresholds does the model proceed to production. Specific error rates, response times, compliance checks.
Production deployment with gradual rollout
Two techniques minimize risk when releasing AI to live systems.
Shadow Mode (Dark Launch)
The new AI model runs in parallel with the existing system, processing real-time data but not affecting live transactions or customer decisions. The new model's outputs are recorded and compared against the current system's decisions and actual outcomes.
This allows validation in production conditions, with real data, real traffic, real user behavior, without any operational risk. Teams can observe false positive rates, latency, edge cases, and model stability over weeks before switching to it live.
Canary Releases
The AI model is deployed to a small percentage of users or servers first. If performance metrics stay within acceptable thresholds, the rollout expands incrementally.
This catches issues at small scale before they affect all users. Clear thresholds for acceptable error rates, latency degradation, and system stability determine when to expand the rollout or halt and revert.
What it replaced: Ad-hoc testing and manual approval workflows
Before this structured approach, fintech teams often tested AI models with minimal environment separation. Code moved directly between developer machines, staging systems, and production.
Testing was incomplete or skipped entirely to meet launch timelines. Compliance checks happened after deployment, not before. When problems emerged in production, a spike in false positives, a data breach, a regulatory violation, the response was reactive. Shut down the system. Investigate. Patch. Redeploy. Hope it doesn't happen again.
The three-environment model with gradual deployment replaces this with preventive control. It adds time to rollout but removes the operational and regulatory risk of discovering problems after customers are affected.
What it didn't solve: Model drift, bias, and continuous retraining
Deploying an AI system successfully doesn't mean it stays successful.
Model Drift
AI models degrade over time as real-world data patterns change. A fraud detection model trained on 2024 transaction patterns may perform poorly on 2026 transactions if customer behavior, fraud tactics, or market conditions have shifted. The deployment framework ensures the model works at launch; it doesn't prevent performance decay months or years later. Fintech operators must establish continuous monitoring and retraining schedules, defining when models are retrained, how often, and on what data.
Algorithmic Bias and Fairness
If training data contains historical bias, for example, loan defaults correlated with demographic factors, the model can perpetuate or amplify that bias in production. This leads to unfair or discriminatory outcomes. Testing in staging can catch some bias issues, but not all. Ongoing audits of model decisions for fairness and compliance are necessary throughout the model's life. This piece doesn't cover how to measure or mitigate bias. That's a separate governance problem beyond deployment.
Explainability
For many fintech applications, regulators and customers require understanding why an AI made a particular decision. Why a loan was denied. Why a transaction was flagged as suspicious. Some AI models, neural networks, ensemble methods, are difficult to explain. Testing in staging doesn't solve this; it only reveals the problem. Fintech teams often must choose between highly accurate but opaque models and less accurate but explainable ones. The deployment framework doesn't make this trade-off. Operators do.
Data Privacy and Security Breaches
Robust security measures are necessary, encrypted data storage, access controls, audit trails, but are not guaranteed by the deployment framework itself. A breach can still occur. The framework's role is to enforce security architecture and validate it in staging. Ongoing security monitoring and incident response remain essential.
Regulatory Change
Regulations evolve. A model that was compliant in 2025 may violate new rules in 2026. The deployment framework doesn't monitor regulatory change or automatically adapt models. Teams must track regulatory updates and trigger model retraining or redesign when necessary.
How to find yours: Decision framework for your fintech operation
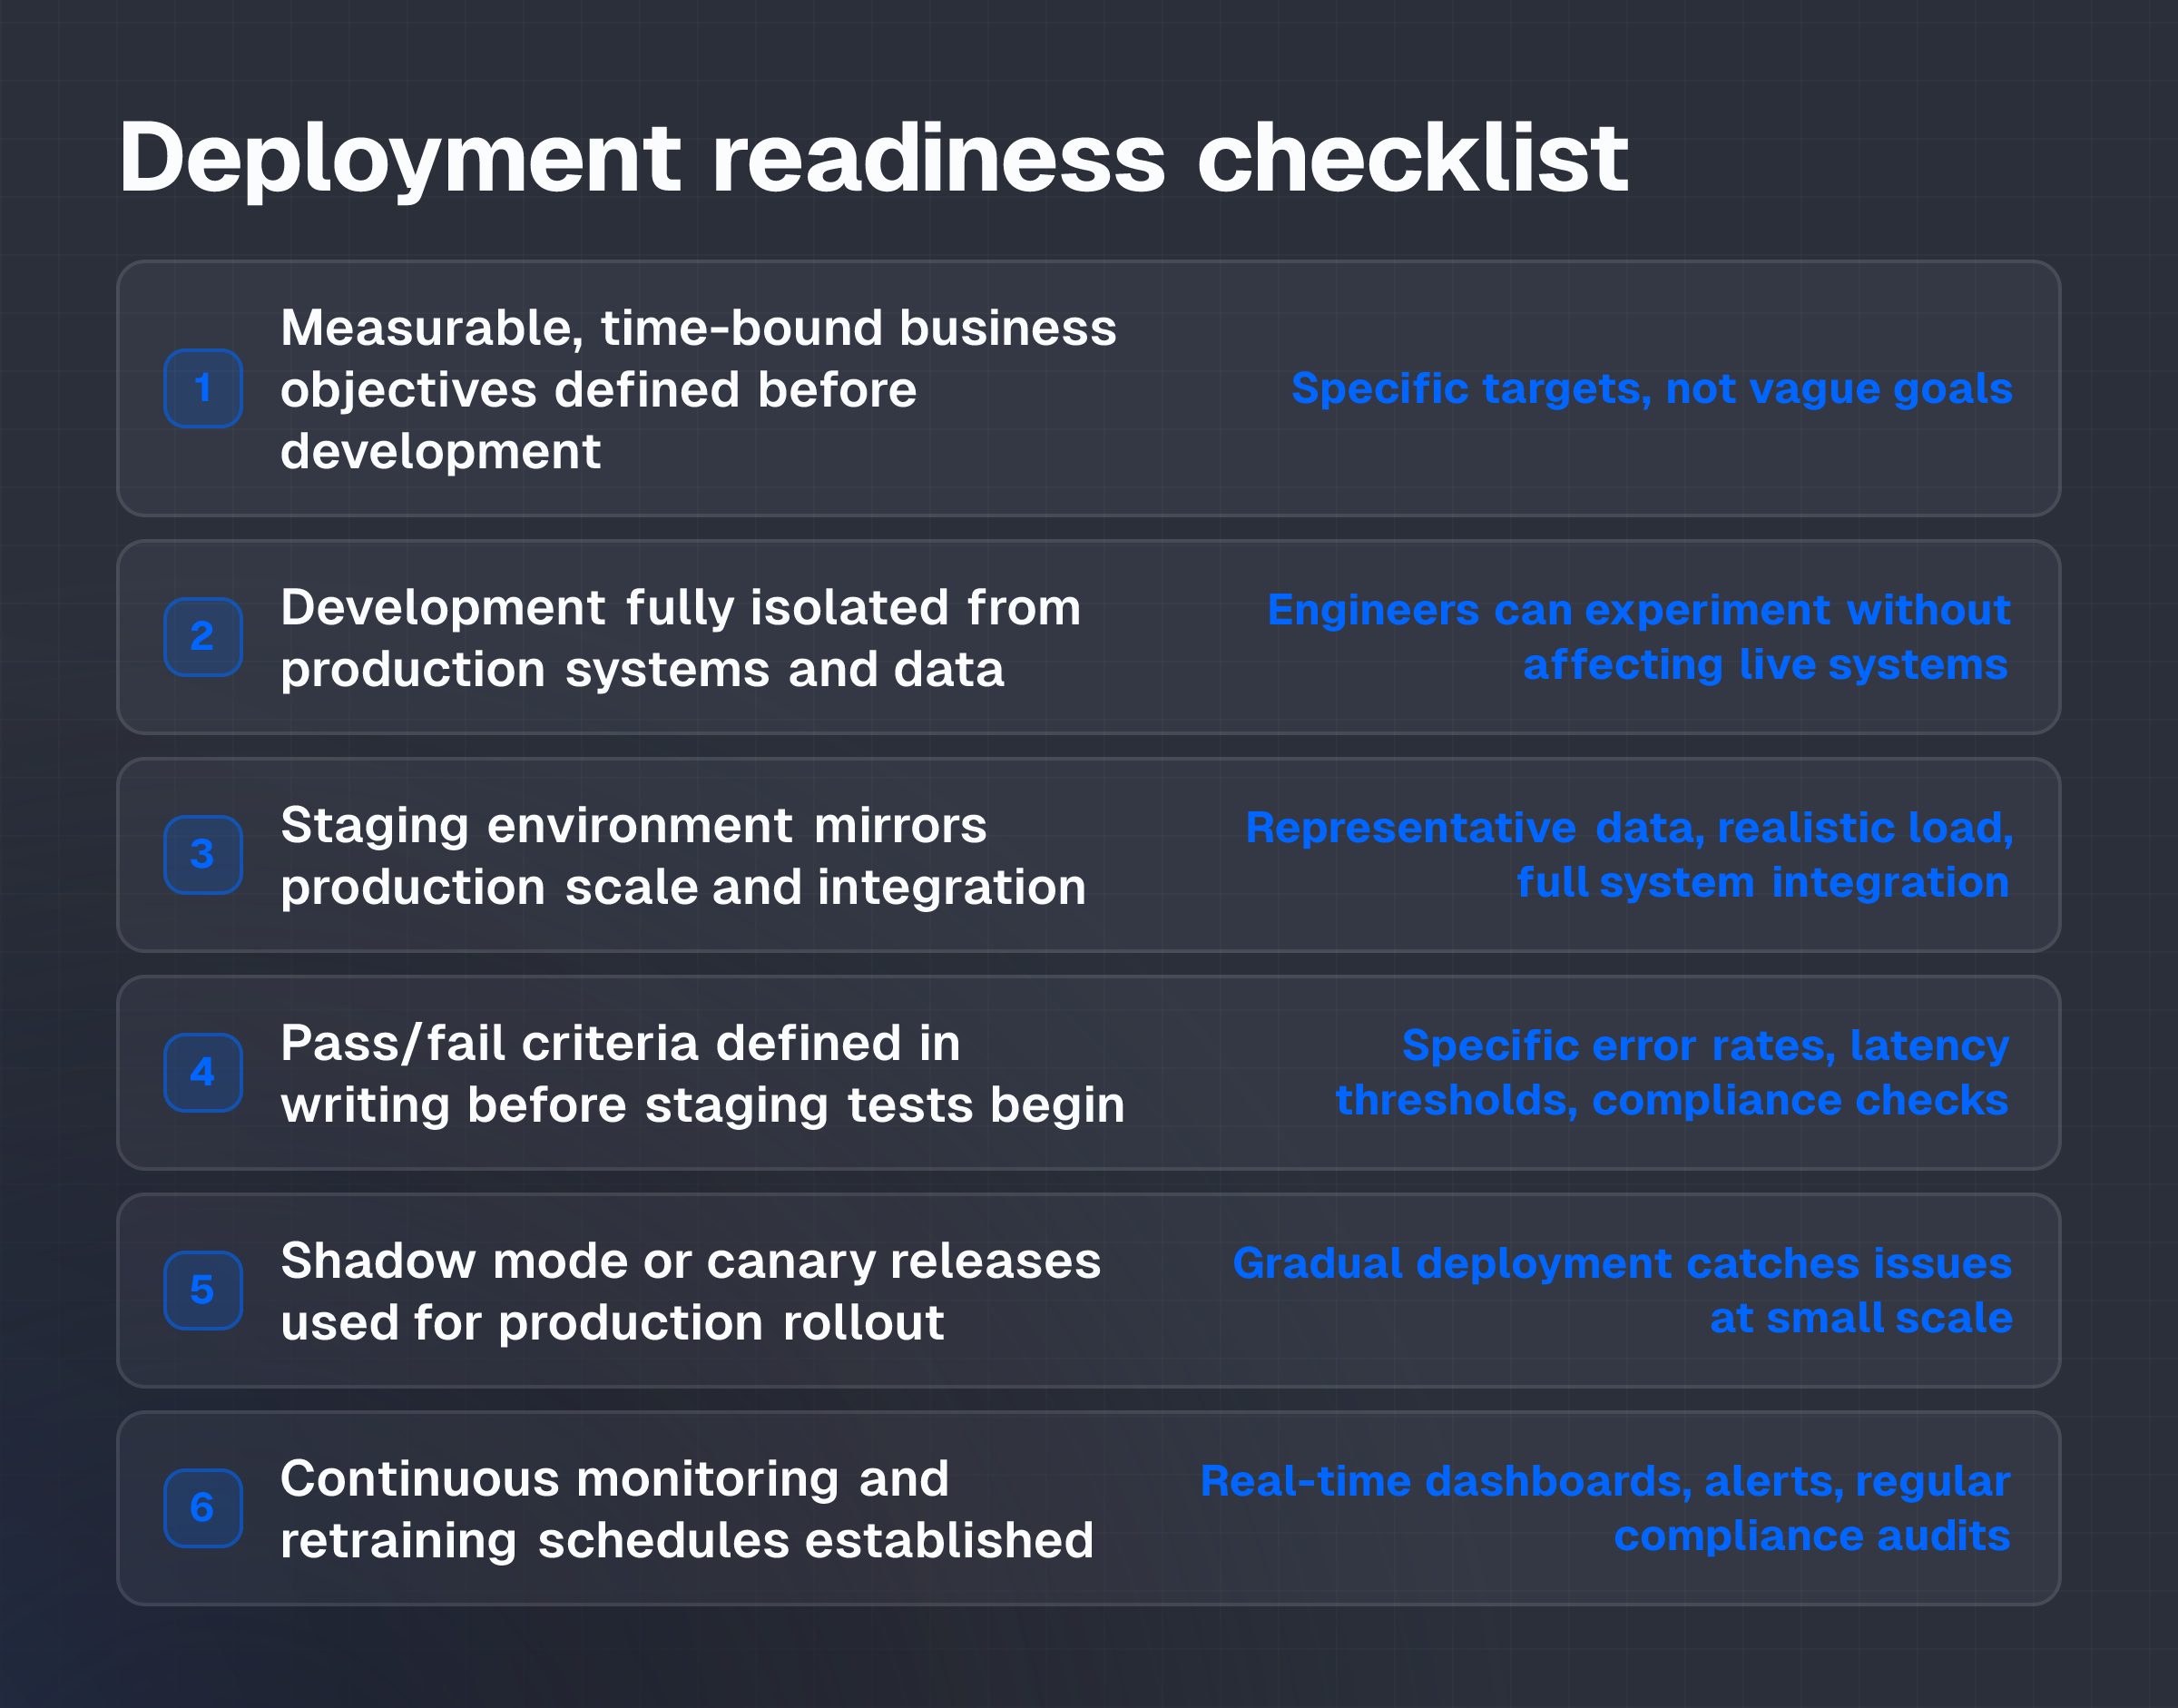
Use this framework to evaluate whether your current AI deployment approach meets these standards.
Are your business objectives measurable and time-bound? Define specific targets before development starts, e.g., "reduce credit default prediction error by 5% within 12 months" rather than "improve credit risk assessment." If your objective is vague, refine it first.
Is development fully isolated from production? Can engineers experiment without affecting staging or live systems? If development code or data touches production, your isolation is incomplete.
Do you have a staging environment that mirrors production? Can you test the AI system with representative data, full system integration, realistic load, security assessment, and compliance checks before going live? If staging is a scaled-down or incomplete replica, you risk missing issues that only appear at production scale or with production data patterns.
Are your staging pass/fail criteria defined in advance? Specific acceptable error rates. Latency thresholds. Compliance audit results. Written down before testing begins. If criteria are vague or decided after testing, you lack objective gates.
Are you using shadow mode or canary releases for production rollout? Or are you deploying all-at-once? Gradual rollout catches issues at small scale. All-at-once risks outages or widespread harm.
Do you have continuous monitoring in place? Real-time dashboards for model performance. Alerts for anomalies. Regular compliance audits. Retraining schedules. If monitoring is manual or absent, you won't detect drift until customers report problems.
If you answer "no" or "unclear" to more than one of these, your deployment process has gaps. Addressing them reduces the likelihood of compliance breaches, outages, or silent performance degradation.
FAQs
What data should I use in staging if I can't use real customer data?
Use anonymized or synthetic data that preserves the statistical properties of real data, the distribution of transaction sizes, customer segments, fraud patterns, without containing identifiable information. The goal is for the AI model to encounter realistic conditions and edge cases, not necessarily the exact records. If your data contains highly sensitive information, anonymization tools and synthetic data generation platforms can help.
How long should shadow mode run before I switch an AI system live?
Shadow mode should run long enough to validate performance across the model's expected scenarios. Normal conditions. Peak load. Rare edge cases. Seasonal variations if applicable. For fraud detection, this might be two to four weeks. For credit scoring, longer. Define the validation criteria, acceptable error rates, latency, compliance metrics, before starting shadow mode, then measure until those criteria are consistently met.
What happens if my AI model fails in production after I deploy it?
You should have a rollback plan defined before deployment. If performance degrades, error rates spike, or compliance violations are detected, reverting to the previous system should be possible quickly, ideally within minutes, not hours. Shadow mode and canary releases reduce the blast radius of failure, but they don't eliminate it. Rollback procedures are essential.
Do I need to involve compliance teams in staging tests?
Yes. Compliance should validate that the AI model's decisions, audit trails, and data handling meet regulatory requirements before production deployment. Leaving compliance checks for after launch risks regulatory violations and fines. Staging is the appropriate place for this validation because it occurs before any customer impact.
How often should I retrain an AI model after it's live?
This depends on your use case, data volatility, and business tolerance for performance decay. Continuous monitoring will reveal when accuracy is declining. Use that signal to trigger retraining. Some models may require monthly retraining; others, quarterly or annual. Define this schedule based on your model's performance monitoring.
Can I skip staging and go directly from development to production?
No. Staging is where you catch issues that don't appear in isolated development environments, integration problems, compliance violations, performance issues at production scale, security vulnerabilities. Skipping staging increases the risk of outages, data breaches, and regulatory violations. The operational and regulatory cost of failure typically far exceeds the time saved by skipping staging.